01Juba, and a download problem
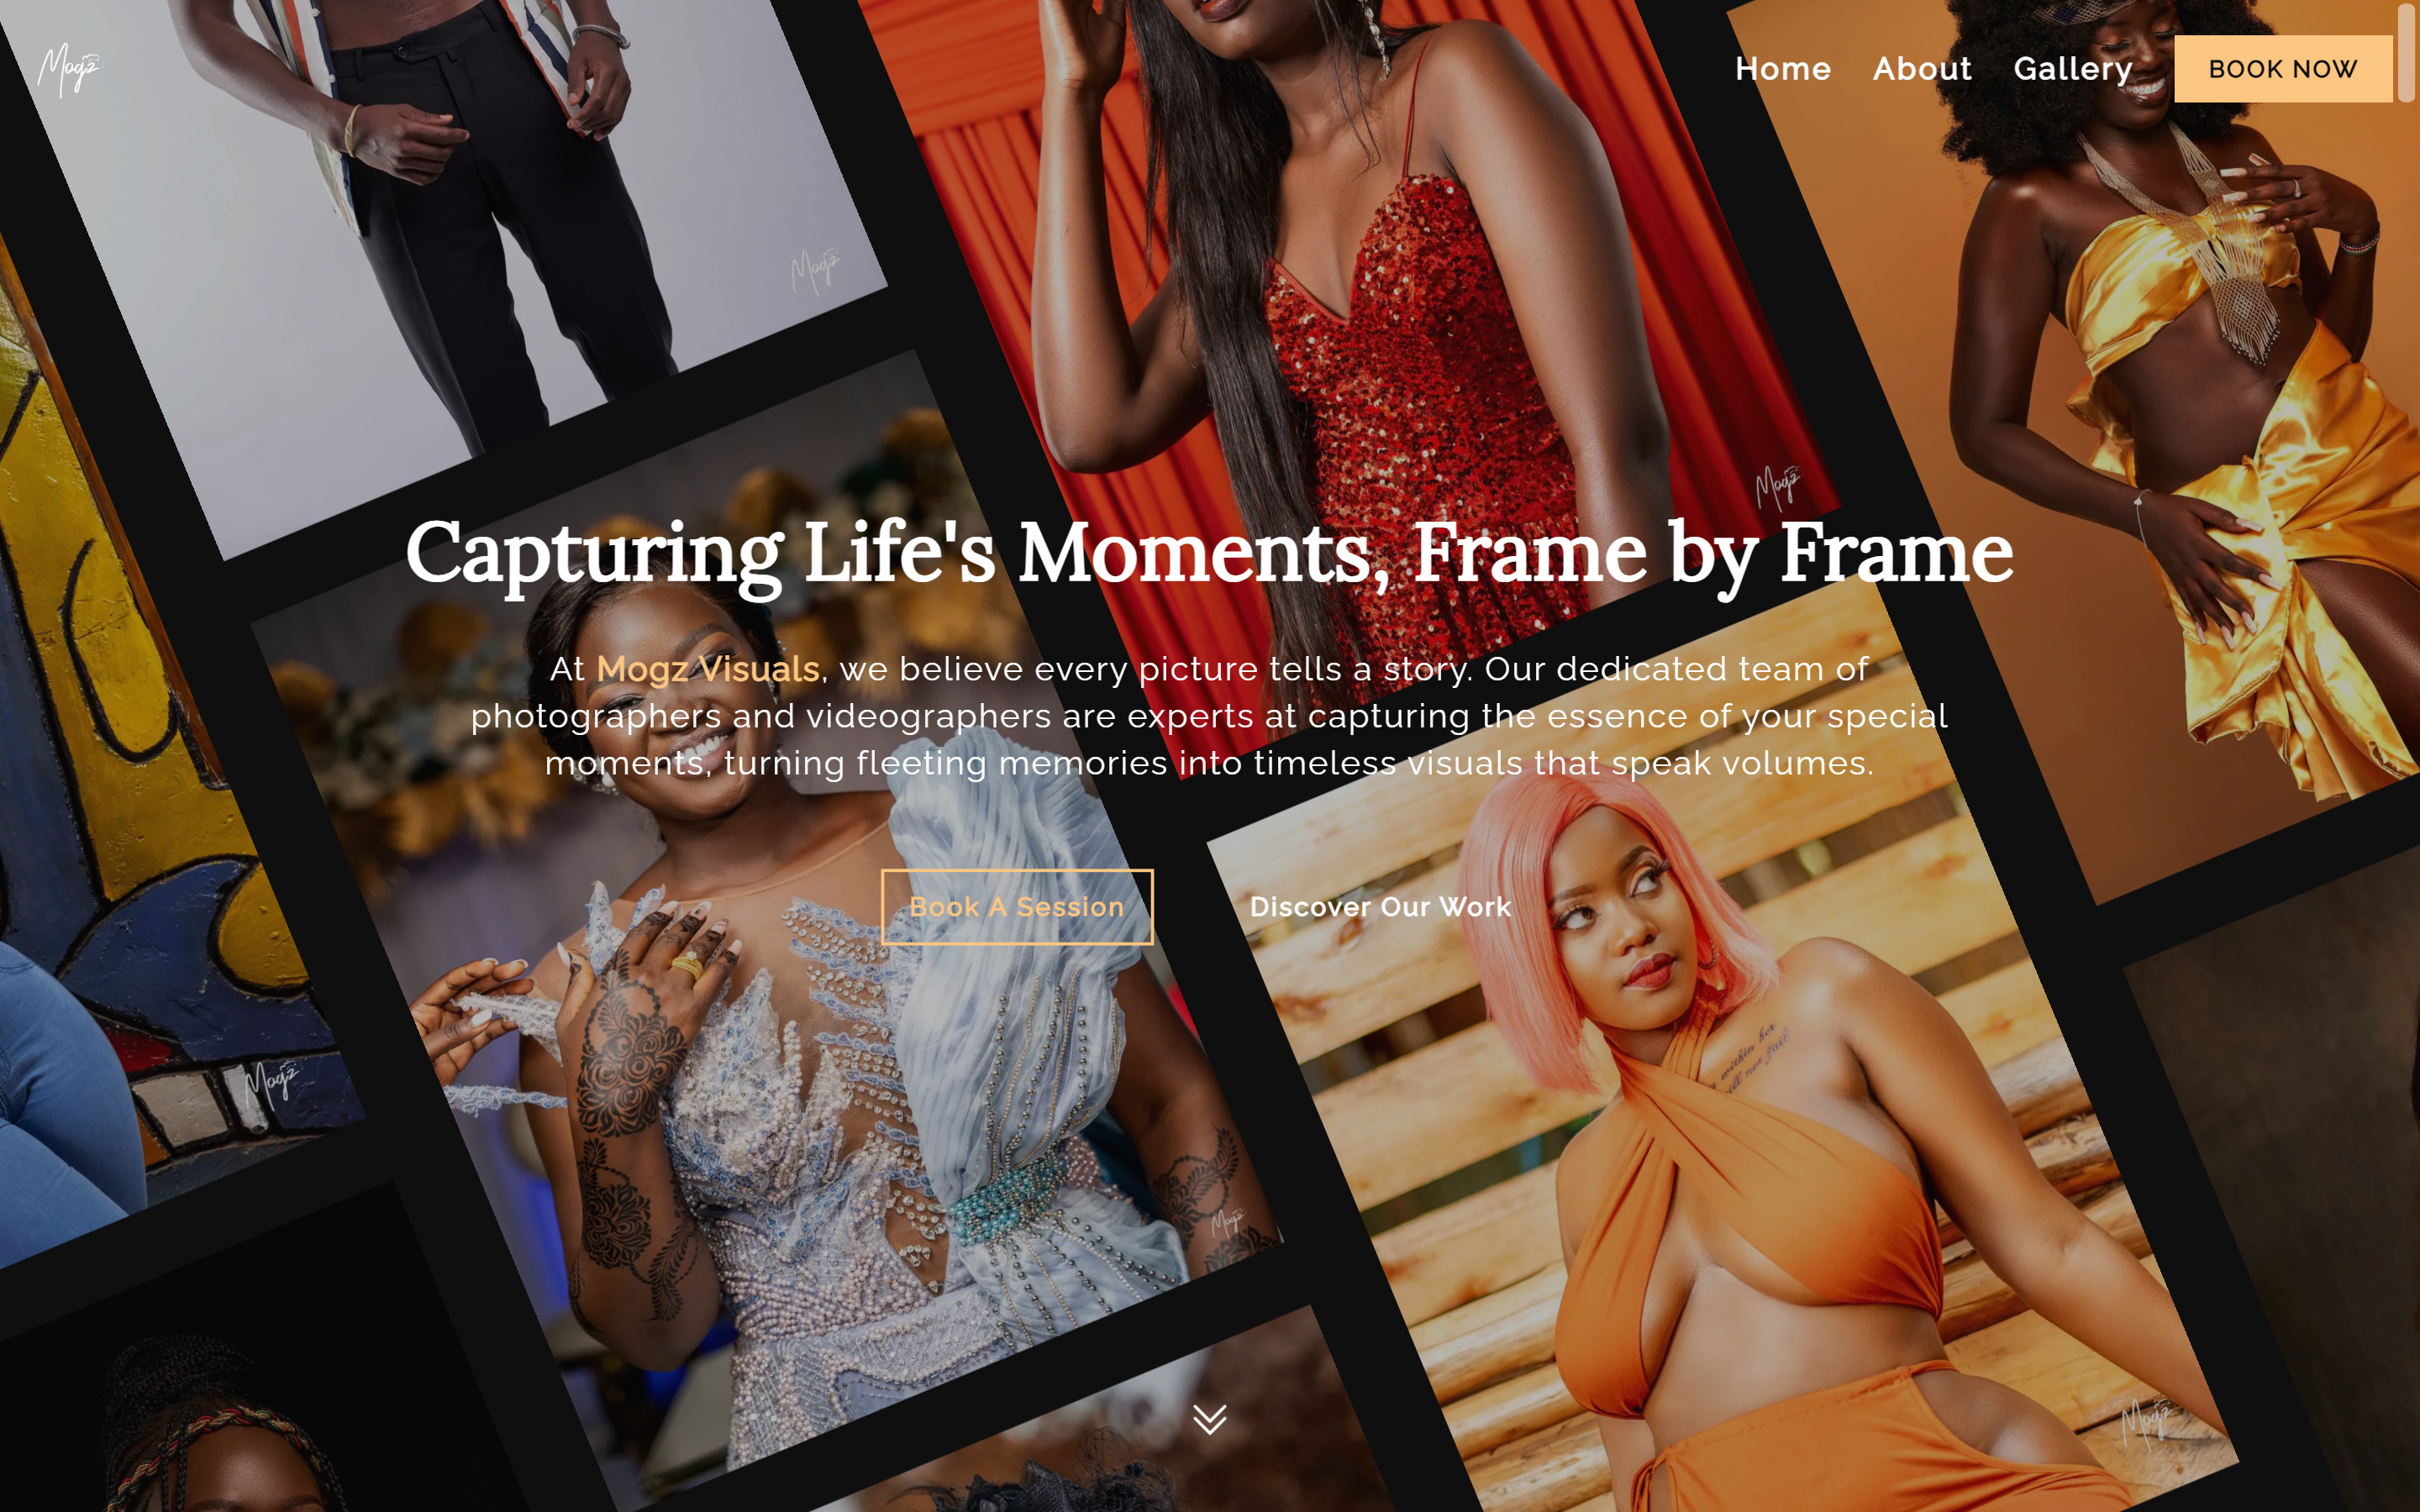
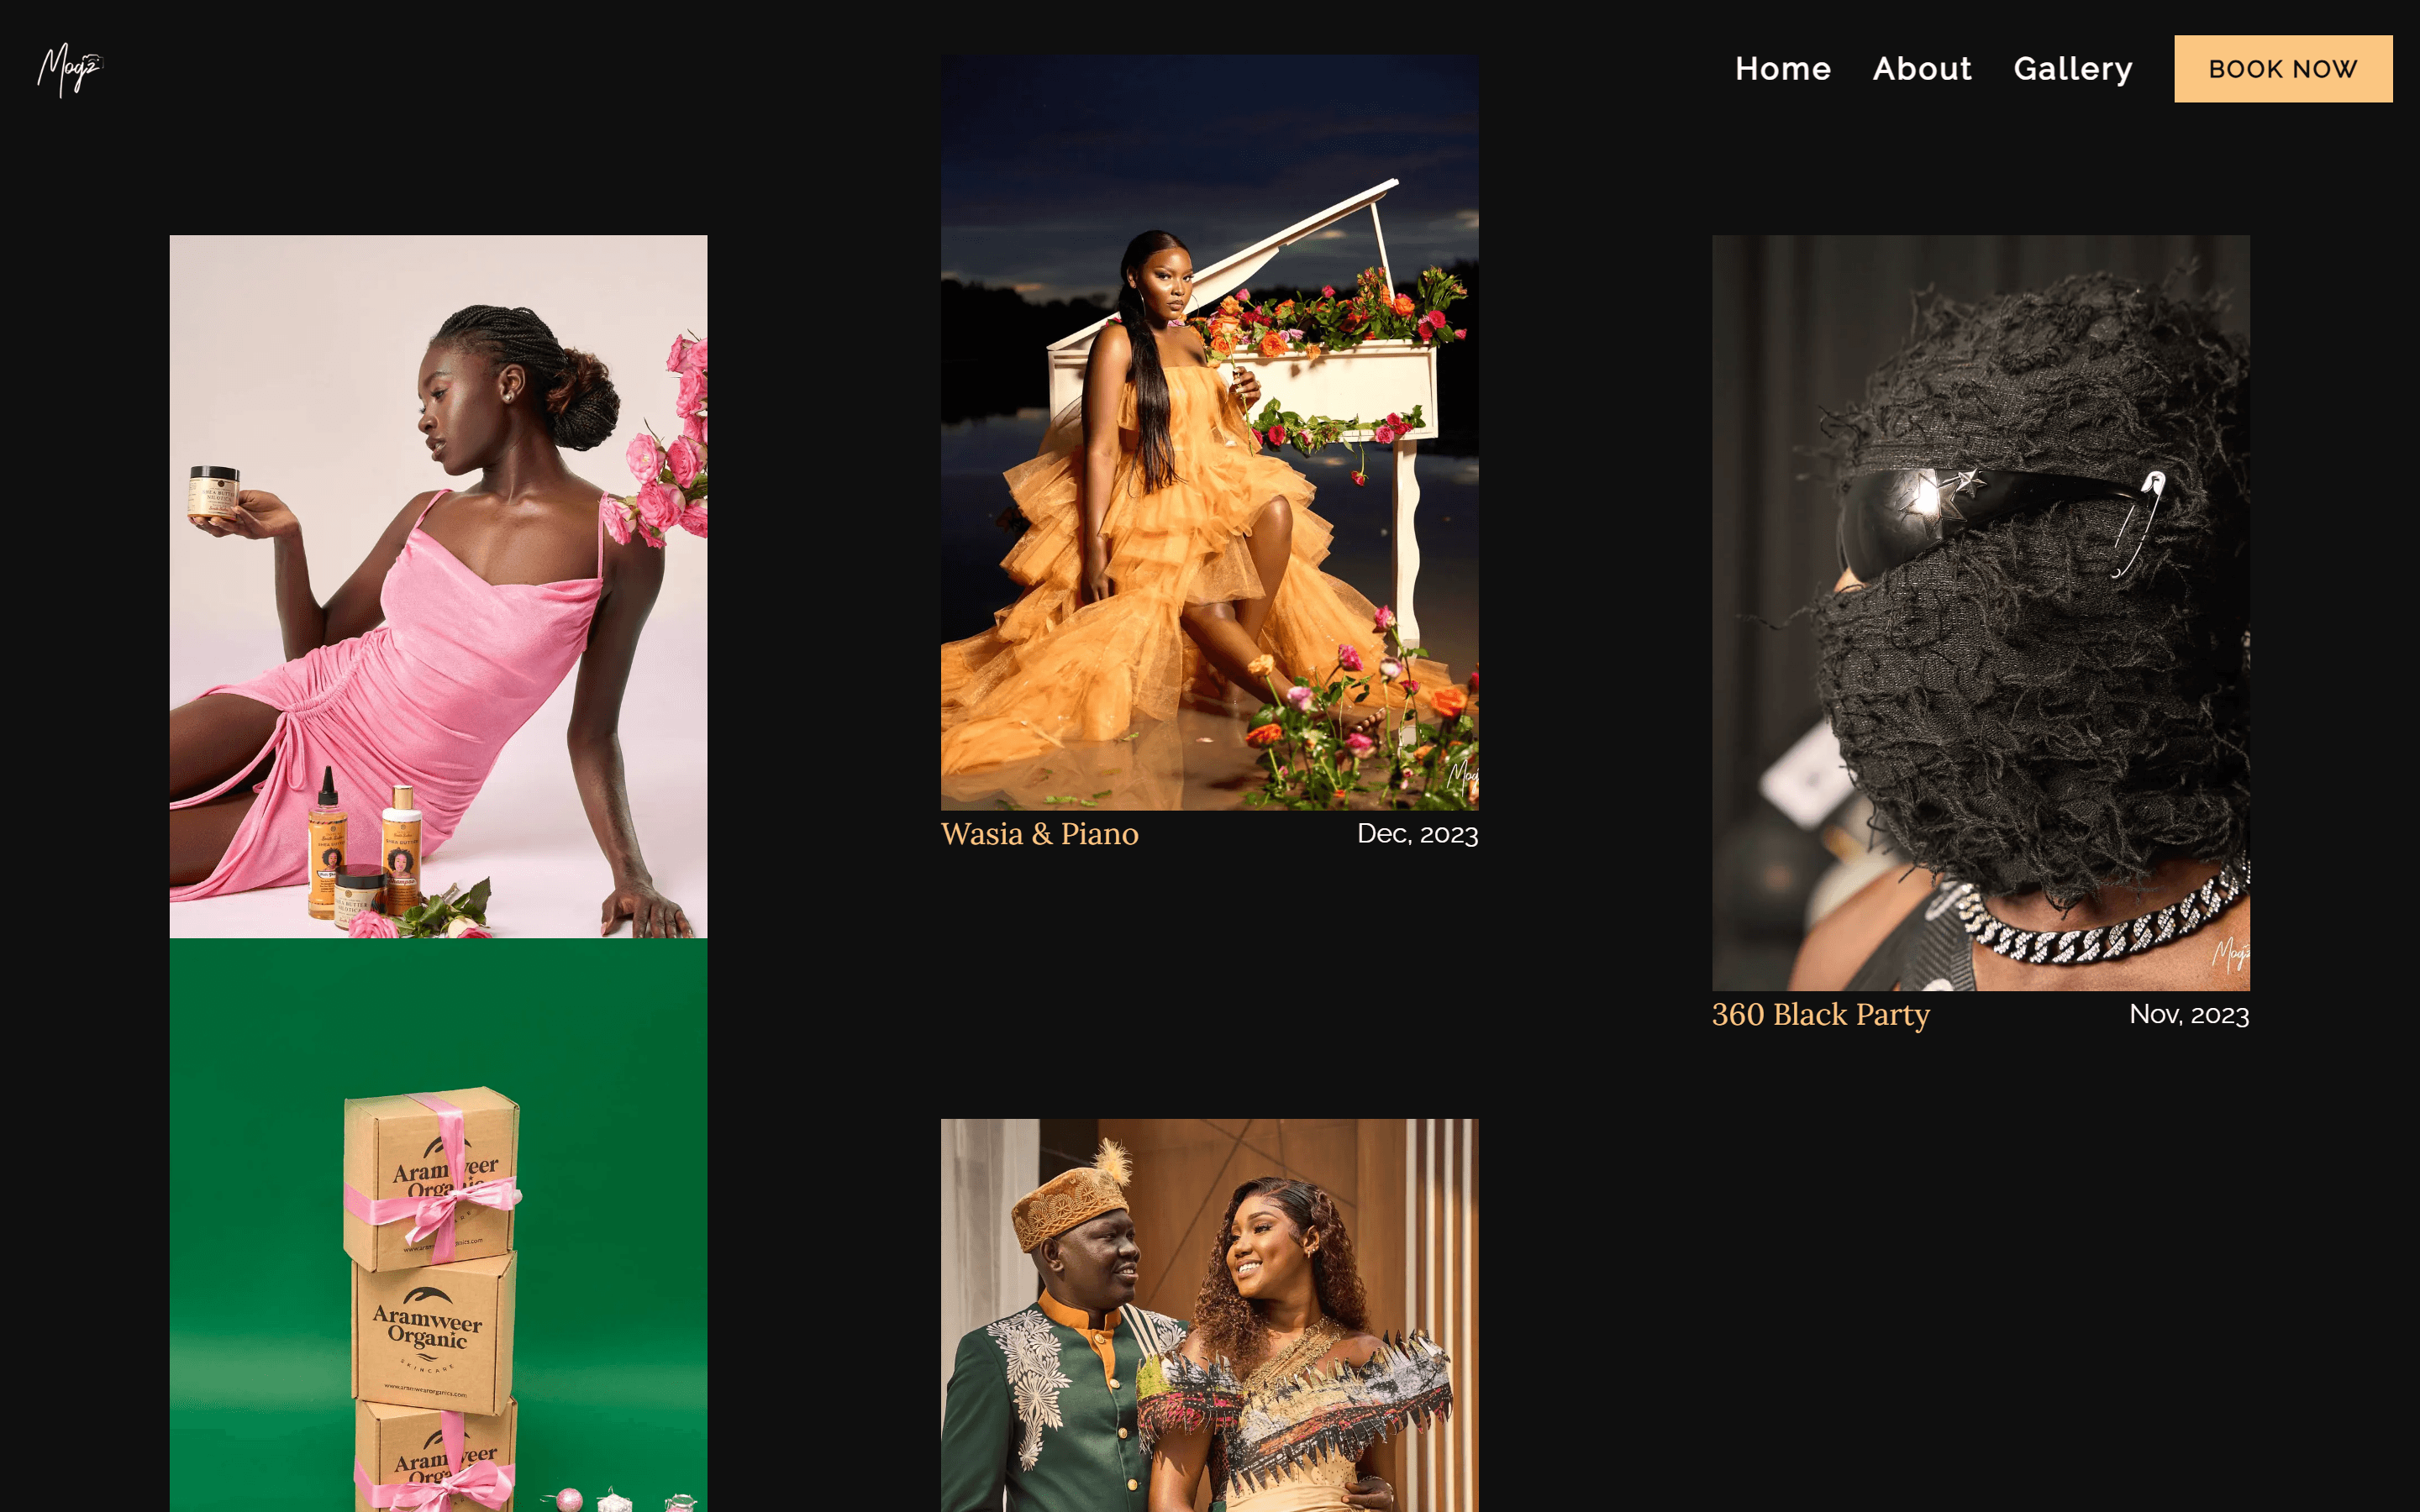
Mogz Visuals is a photography and media studio in Juba, led by Jacob Mogga Kei. The work is good. The website in front of it did not say so. Jacob wanted a site that felt like the photography: immersive to move through, with a private side where clients could view their own shoots and download them without trading file links back and forth.
That second half is what made it interesting to build, because the site had to hand a client a few hundred high-resolution photos as a single download.
02Smooth scrolling against a server-first framework
I wanted the heavy, smooth scroll feel you get from Locomotive Scroll, the kind of momentum that makes a portfolio feel considered. The trouble is that Locomotive is a browser library that takes over the page's scroll container. Next.js with the App Router renders on the server first, where there is no window to take over.
The fix is to keep the library entirely on the client and give it a clear lifecycle. A scroll provider imports Locomotive only in the browser, after the component has mounted, and tunes its smoothness to the viewport. The App Router keeps components alive across navigations, so the provider tears the instance down and rebuilds it whenever the path changes. Sections opt in through a small LocomotiveScrollSection wrapper, which renders them in a tag that carries the data-scroll-section attribute.
const getLerpForViewport = () => {
  const width = window.innerWidth;

  if (width < 768) return 0.14;
  if (width < 1024) return 0.08;
  return 0.05;
};

const getTouchMultiplierForViewport = () => {
  const width = window.innerWidth;

  if (width < 768) return 3.25;
  if (width < 1024) return 3.5;
  return 3;
};

const initializeScroll = async () => {
  if (scrollRef.current) {
    scrollRef.current.destroy();
  }

  const LocomotiveScroll = (await import('locomotive-scroll')).default;
  const scroll = new LocomotiveScroll({
    el: document.querySelector('[data-scroll-container]') as HTMLElement,
    lerp: getLerpForViewport(),
    smooth: true,
    reloadOnContextChange: true,
    tablet: { smooth: true, breakpoint: 1024 },
    smartphone: { smooth: true },
    touchMultiplier: getTouchMultiplierForViewport(),
  });

  scrollRef.current = scroll;
  setScrollInstance(scroll);
};

useEffect(() => {
  initializeScroll();

  return () => {
    if (scrollRef.current) {
      scrollRef.current.destroy();
      scrollRef.current = null;
      setScrollInstance(null);
    }
  };
  // eslint-disable-next-line react-hooks/exhaustive-deps
}, [pathname]);03An about section that drifts past you
For the about section I did not want a grid. I wanted photos scattered the way they might be on a table, then sliding past at different speeds as you scroll. To place them I borrowed the golden angle, the same 137.5 degrees plants use to space leaves so they do not shadow each other. It spreads images evenly around the center without clumping them, and a little random jitter keeps it from looking like a math exercise. Each image then gets its own parallax speed and scale.
// GOLDEN SPIRAL ALGORITHM (Nature's way of distributing items in a circle)
// 137.5 degrees is the "golden angle"
const angle = i * 137.5 * (Math.PI / 180);

// Radius increases with index to spiral outward,
// BUT we add a base offset to keep the center clear for text.
// normalize 'i' from 0 to 1
const normalizedIndex = i / Math.max(images.length - 1, 1);

// Min radius (safe zone) = 30% width. Max radius = 45% width.
const radiusX = 30 + normalizedIndex * 15;
// Vertical radius stretched because container is tall (200vh)
const radiusY = 35 + normalizedIndex * 20;

// Add random jitter so it doesn't look like a perfect math spiral
const randomX = (Math.random() - 0.5) * 10;
const randomY = (Math.random() - 0.5) * 10;

// Calculate Center Positions
const x = 50 + Math.cos(angle) * radiusX + randomX;
const y = 50 + Math.sin(angle) * radiusY + randomY;

return {
  src,
  top: Math.max(5, Math.min(95, y)), // Clamp to 5-95%
  left: Math.max(5, Math.min(95, x)), // Clamp to 5-95%
  width: 260 + Math.random() * 140, // Random width 260-400px
  speed: Math.random() * 1.5 + 0.5, // Parallax speed
  scaleType: i % 2 === 0 ? 'grow' : 'shrink',
  initialScale: 0.8 + Math.random() * 0.4,
  zIndex: 10 + i,
} as ImageConfig;04A lock that lived on a public shelf
The private side started with a lock that looked right and was not. Sanity's free plan has no private datasets, so every published document is readable by anyone who knows the project ID, and each private collection kept its password in a field on that document. The route that checked it compared the two strings in constant time with crypto.timingSafeEqual. The comparison was correct, and it did not matter. Anyone could read the answer from the dataset and skip the check. On a match, the server encrypted a small payload, the browser wrote its own access cookie from it, and the page trusted that cookie.
The fix had to work with the plan I had, since there was no private dataset to move things into. Sanity serves a document whose ID contains a dot only to an authenticated request, even in a public dataset. So each code now lives in a companion document named collectionSecret.<collection _id>, and the site reads it with a server-only token that never reaches the browser. The published collection document no longer holds a code at all. The comparison now hashes both sides before calling timingSafeEqual. Hashing also removes the length check the old route needed to keep that call from throwing.
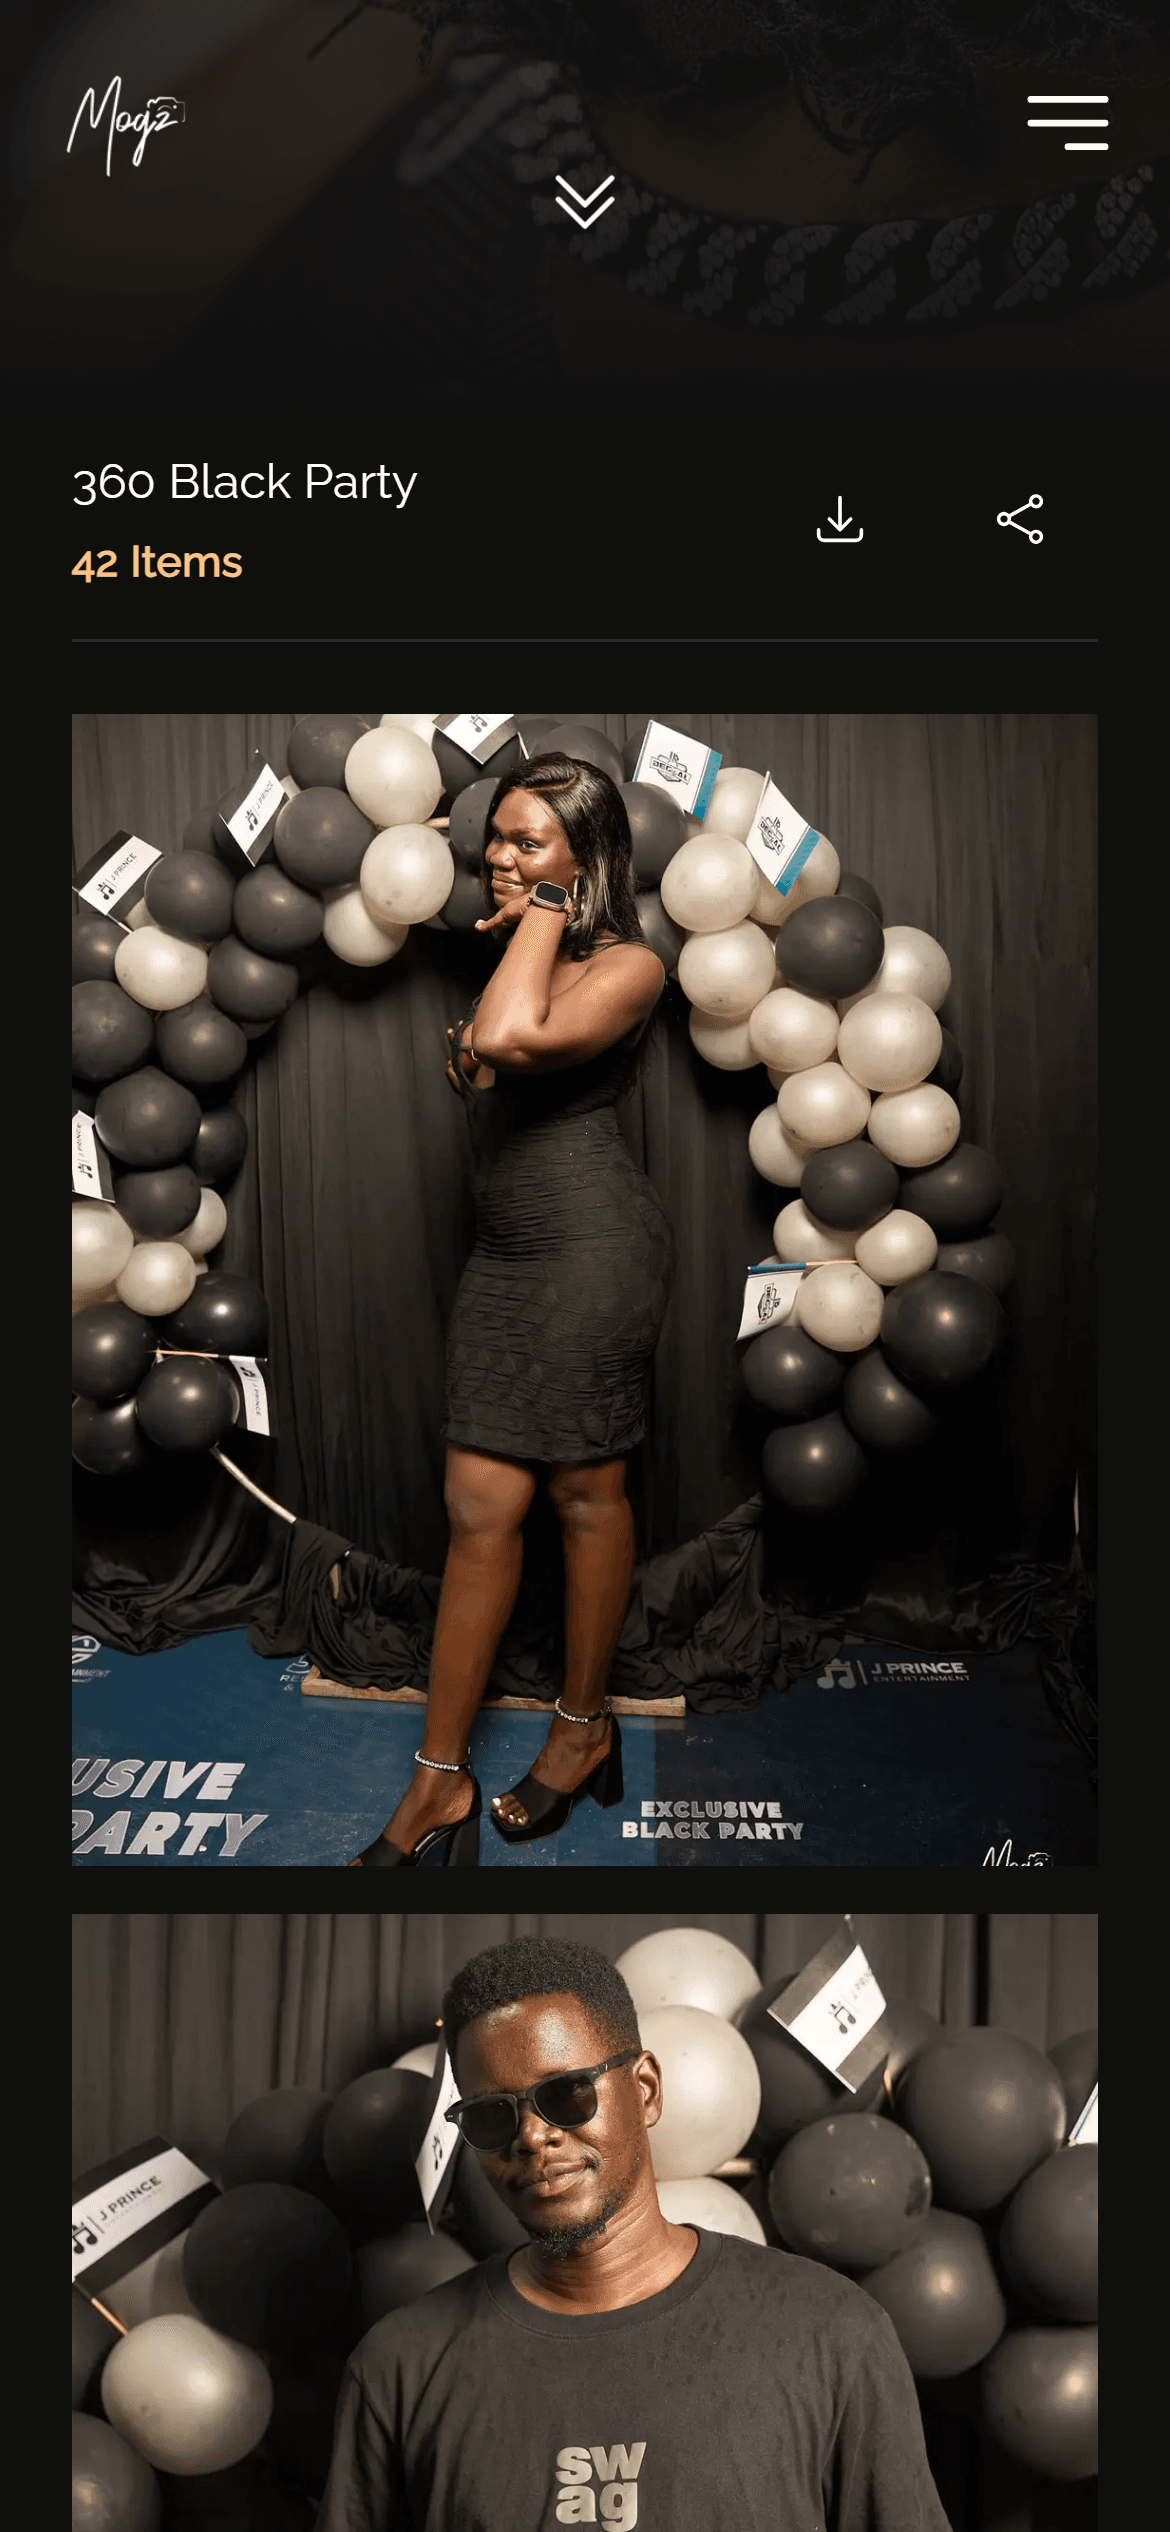
A correct code gets an HMAC-signed, httpOnly cookie that is scoped to that one collection and expires after an hour. Every server path that returns private images checks that cookie before it touches Sanity. Those paths are the gallery segments, the download info, and the download itself. Anyone with a private link still sees the collection hero, with its cover, title, and date, and an Unlock button where the gallery would start. The gallery query runs only after the server has validated the cookie for that exact collection.
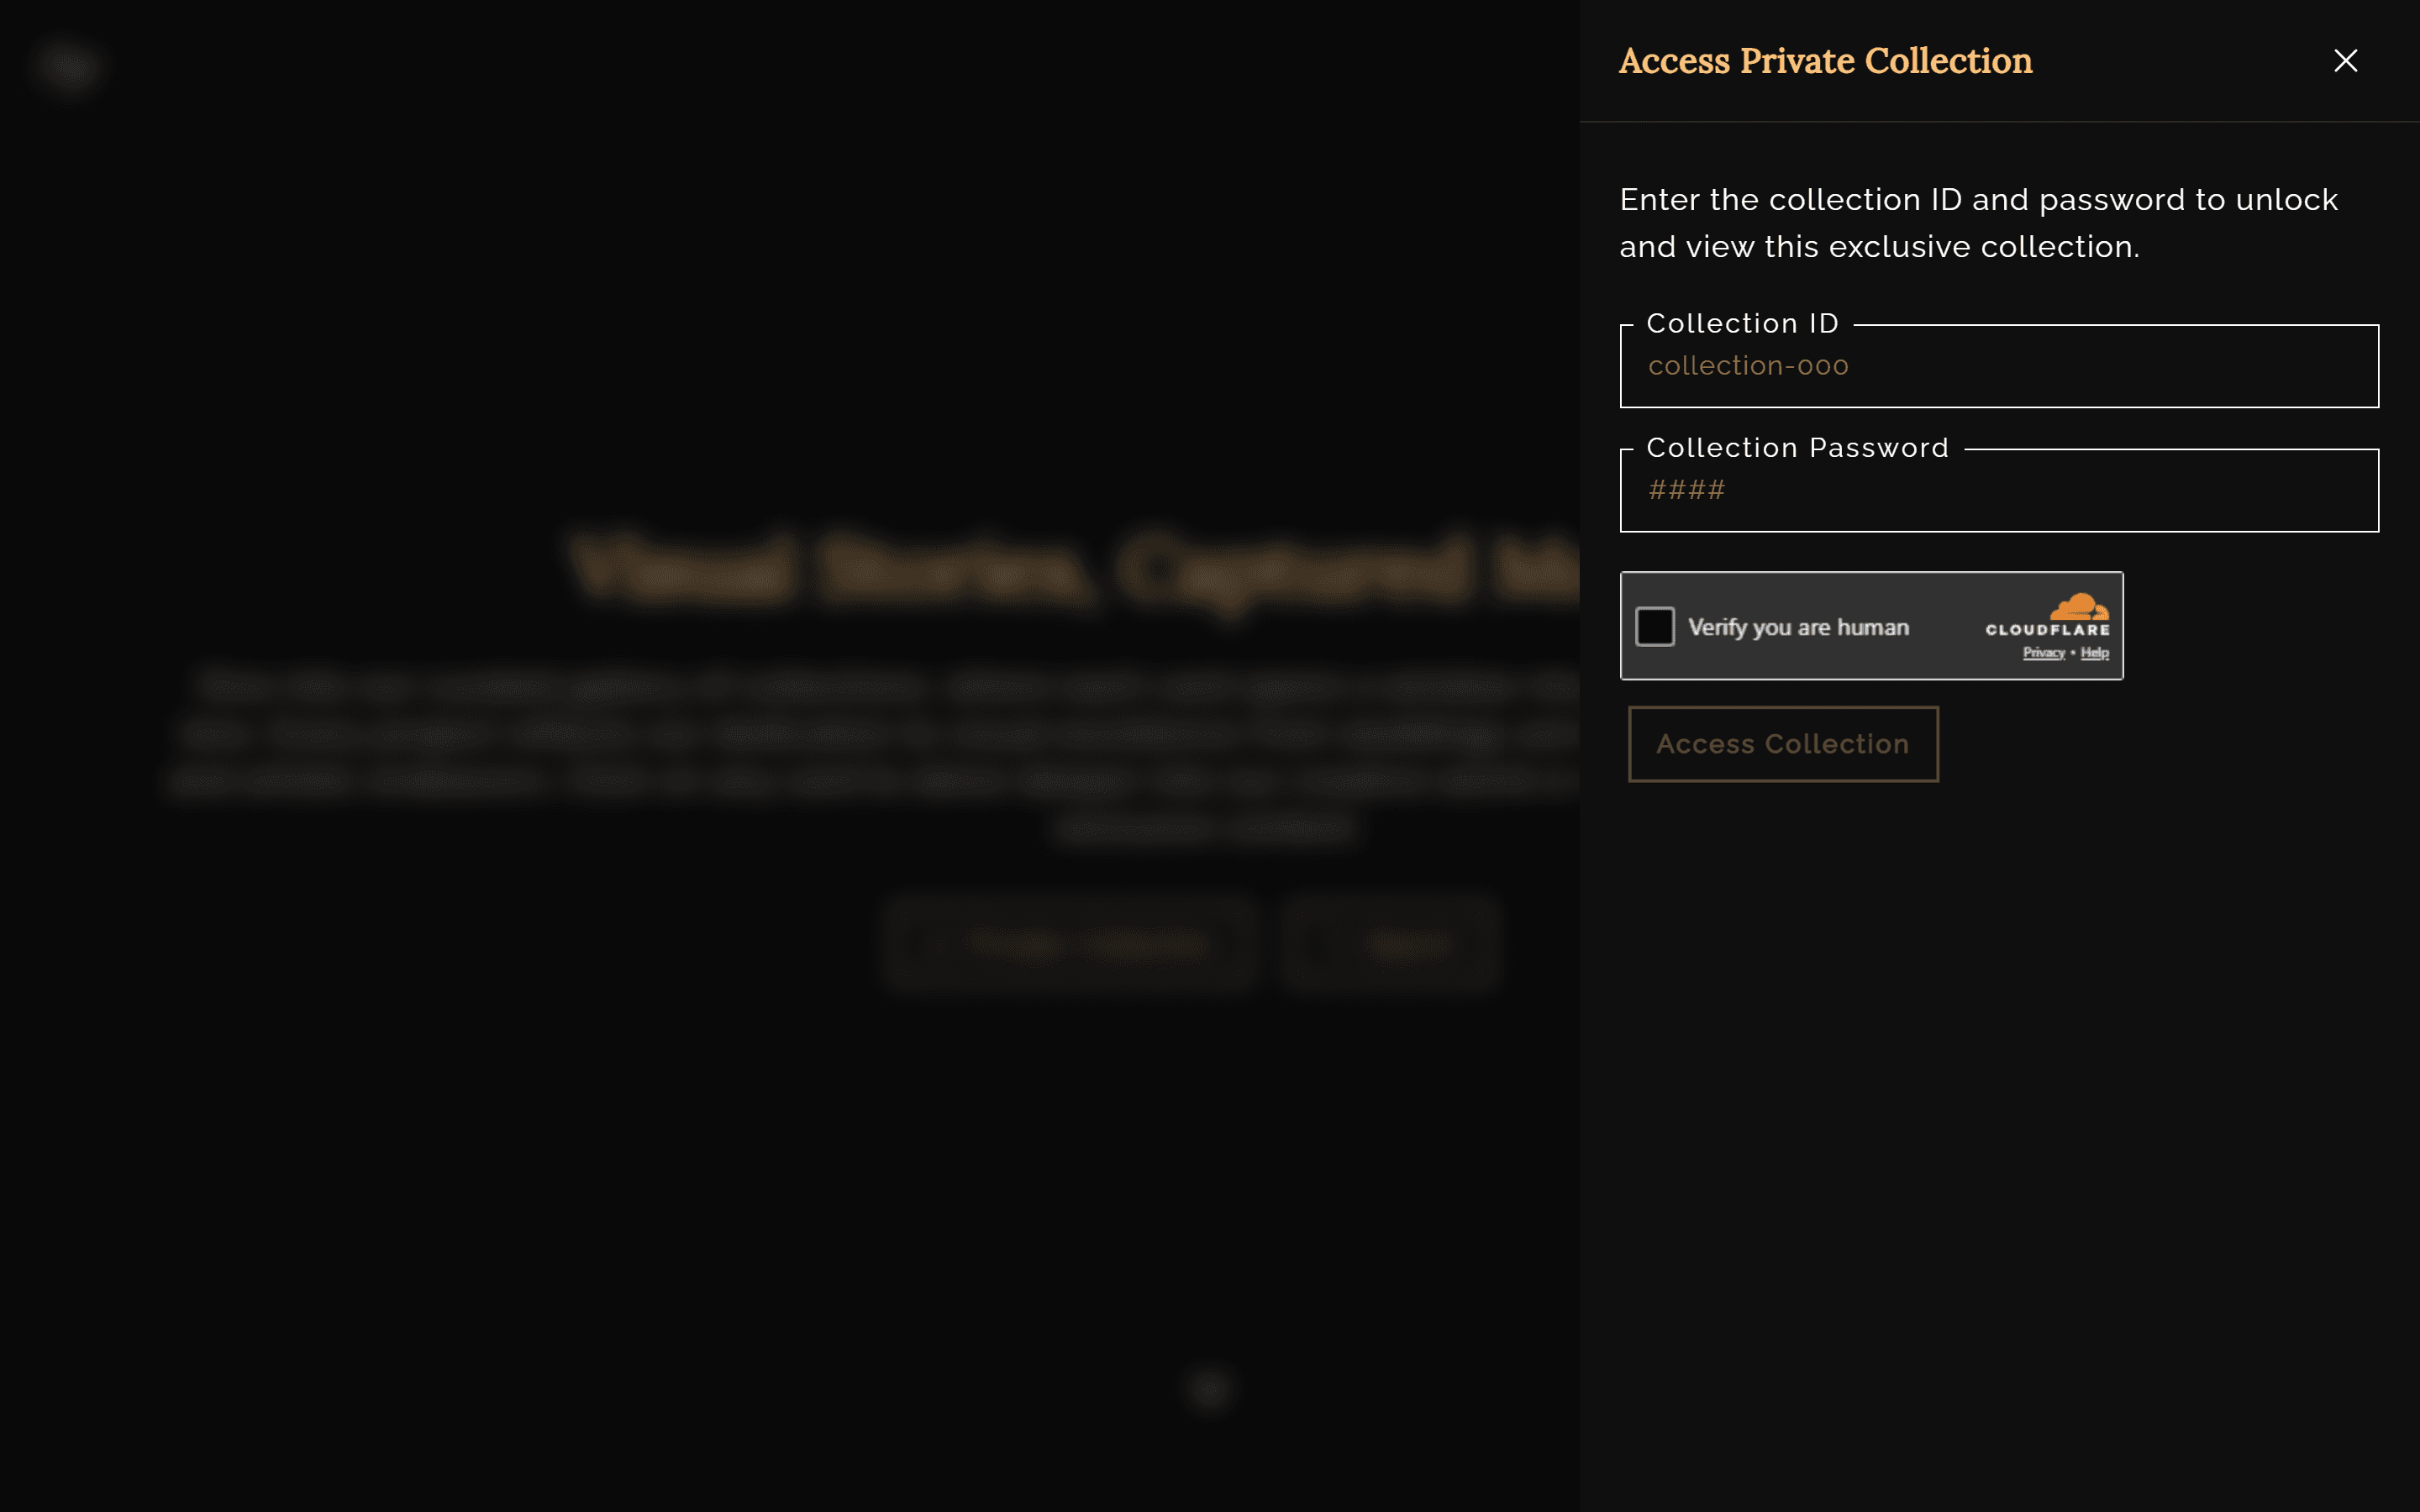
Guesses are rate limited per address, and wrong codes are also counted per address and collection, and per collection overall. Each check reserves a slot before it runs and gives it back unless the code was wrong.
Checking a code
// Compare digests so the comparison is constant-time regardless of length.
const digest = (value: string) => createHash('sha256').update(value).digest();

export const accessCodesMatch = (submitted: string, stored: string) =>
  timingSafeEqual(digest(submitted), digest(stored));

// ...

const secret = await client.getDocument<CollectionSecret>(
  collectionSecretId(collection._id),
);

if (secret) {
  // The companion is bound to this exact collection by its _id and
  // collectionId. Its uniqueId copy is informational only: comparing it would
  // lock clients out whenever an editor regenerates the ID in an unpublished
  // draft.
  const consistent =
    secret._type === COLLECTION_SECRET_TYPE &&
    secret.collectionId === collection._id &&
    typeof secret.accessCode === 'string' &&
    secret.accessCode.length > 0;

  if (!consistent) {
    console.warn('[Access] Companion document is inconsistent', {
      collectionDocumentId: collection._id,
    });
    accessCodesMatch(submittedCode, '');
    return { ok: false };
  }

  return accessCodesMatch(submittedCode, secret.accessCode as string)
    ? { ok: true, uniqueId: collection.uniqueId }
    : { ok: false };
}05Moving the codes without changing them
The Studio had to change with it. The collection's Access code field now reads and writes the companion document instead of the collection. Editors still reveal, copy, and change a code the way they did before. Each save applies only if the companion is still at the revision the editor loaded, so two editors cannot silently overwrite each other. I hid the companion type from the desk, from search, and from every document action. Duplicating one in the Studio would copy its code into a document with an ordinary ID, and a document with an ordinary ID is public.
Then the codes had to move. Clients already had theirs, sent in emails and messages, and I did not want to hand out new ones to fix my own mistake. The migration script is a dry run by default and refuses to write without a production flag. A create never overwrites a companion that already exists, and every other write applies only if the document is still at the revision the script inspected. I ran it in stages: back up the dataset, migrate one collection and check it, copy all the codes unchanged and check again, and only then clear the old public fields. During that window, the site fell back to the old field for any collection that had no companion yet, so no client was locked out partway through. The verify step now reports zero codes readable without a token, through both the API and the CDN. It also requests a few dotted IDs directly instead of trusting a count.
if (mode === 'unset-public') {
  // Each target is a single document version whose code the companion holds,
  // cleared only if neither it nor the companion has changed since this run
  // looked at them. Versions sharing a companion go in one transaction with a
  // single guard on the companion: a second guard would see the revision the
  // first one produced.
  const targets = plan.unsetTargets
  const byCompanion = new Map<string, typeof targets>()
  for (const target of targets) {
    byCompanion.set(target.companionId, [...(byCompanion.get(target.companionId) ?? []), target])
  }
  const groups = [...byCompanion.values()]
  for (let i = 0; i < groups.length; i += 25) {
    const tx = client.transaction()
    for (const group of groups.slice(i, i + 25)) {
      const {companionId, companionRev} = group[0]
      // A no-op write that fails if the companion changed or no longer exists.
      tx.patch(companionId, (patch) =>
        patch.ifRevisionId(companionRev).setIfMissing({schemaVersion: 1}),
      )
      for (const target of group) {
        tx.patch(target.documentId, (patch) =>
          patch.ifRevisionId(target.expectedRev).unset(['password']),
        )
      }
    }
    await tx.commit()
}The images are not private. On the free plan, anyone who queries the public dataset can still read a private collection's photos and metadata. The lock protects the codes and the gallery pages that need one. Making the images themselves private would take a plan with private datasets, which the free plan does not have.
06Handing over an entire shoot
The hardest part of the whole project was the download. A client wants their entire gallery as one file, and that can be hundreds of large images.
Phase one did it all in the browser: fetch every image, zip it in memory with JSZip, hand over the file. That was fine until a wedding collection of more than 850 high-resolution photos came through. The browser's main thread choked, and the page froze while it tried to hold the whole archive in memory.
Phase two pushed the heavy work off the main thread into a Web Worker. Comlink sat in between as the RPC bridge, so the main thread could call into the worker like a normal async function. I also split the download into 100-image chunks, so a failed chunk did not force the client to rebuild the chunks it had already received. That held. But it was still asking the client's device to do work the server was better placed to handle.
The current version moves archive creation to the server. buildArchiveFile fetches images from the CDN and appends their streams to a zip file on disk, so it does not hold the full gallery in memory. createZipResponse then streams the finished file to the client. The file name includes a hash of the collection's image list, so a repeat download can reuse a cached archive. While a new archive is being built, the browser listens to a progress stream. When preparation finishes, that stream returns a short-lived signed token that the download request redeems. The worker and 100-image chunks still ship as the download-in-parts fallback when one large server stream is the wrong fit.
const archive = archiver('zip', {
  zlib: { level: 0 },
  forceZip64: false,
  highWaterMark: 1024 * 1024,
});

const fileOutput = fs.createWriteStream(outputPath, {
  highWaterMark: 1024 * 1024,
});

// ...

archive.pipe(fileOutput);

// ... each image is fetched in batches, then streamed straight in:

const res = await fetch(img.url, { signal });
if (!res.ok) {
  console.warn(
    `[Stream] HTTP ${res.status} for ${filename}, skipping.`,
  );
  return null;
}

if (!res.body) {
  return null;
}

// @ts-ignore Readable.fromWeb is available in the runtime used by Next.
const stream = Readable.fromWeb(res.body);
return { name: filename, stream };

// ...

archive.append(result.value.stream, { name: result.value.name });The route also checks a cached file before serving it. It verifies a ZIP local-file-header signature at the front and looks for an end-of-central-directory signature near the tail. That catches an obvious bad or truncated build, but it is not a full integrity check. The archive fetcher only accepts images from Sanity's CDN, and the step that prepares an archive is rate limited per IP.
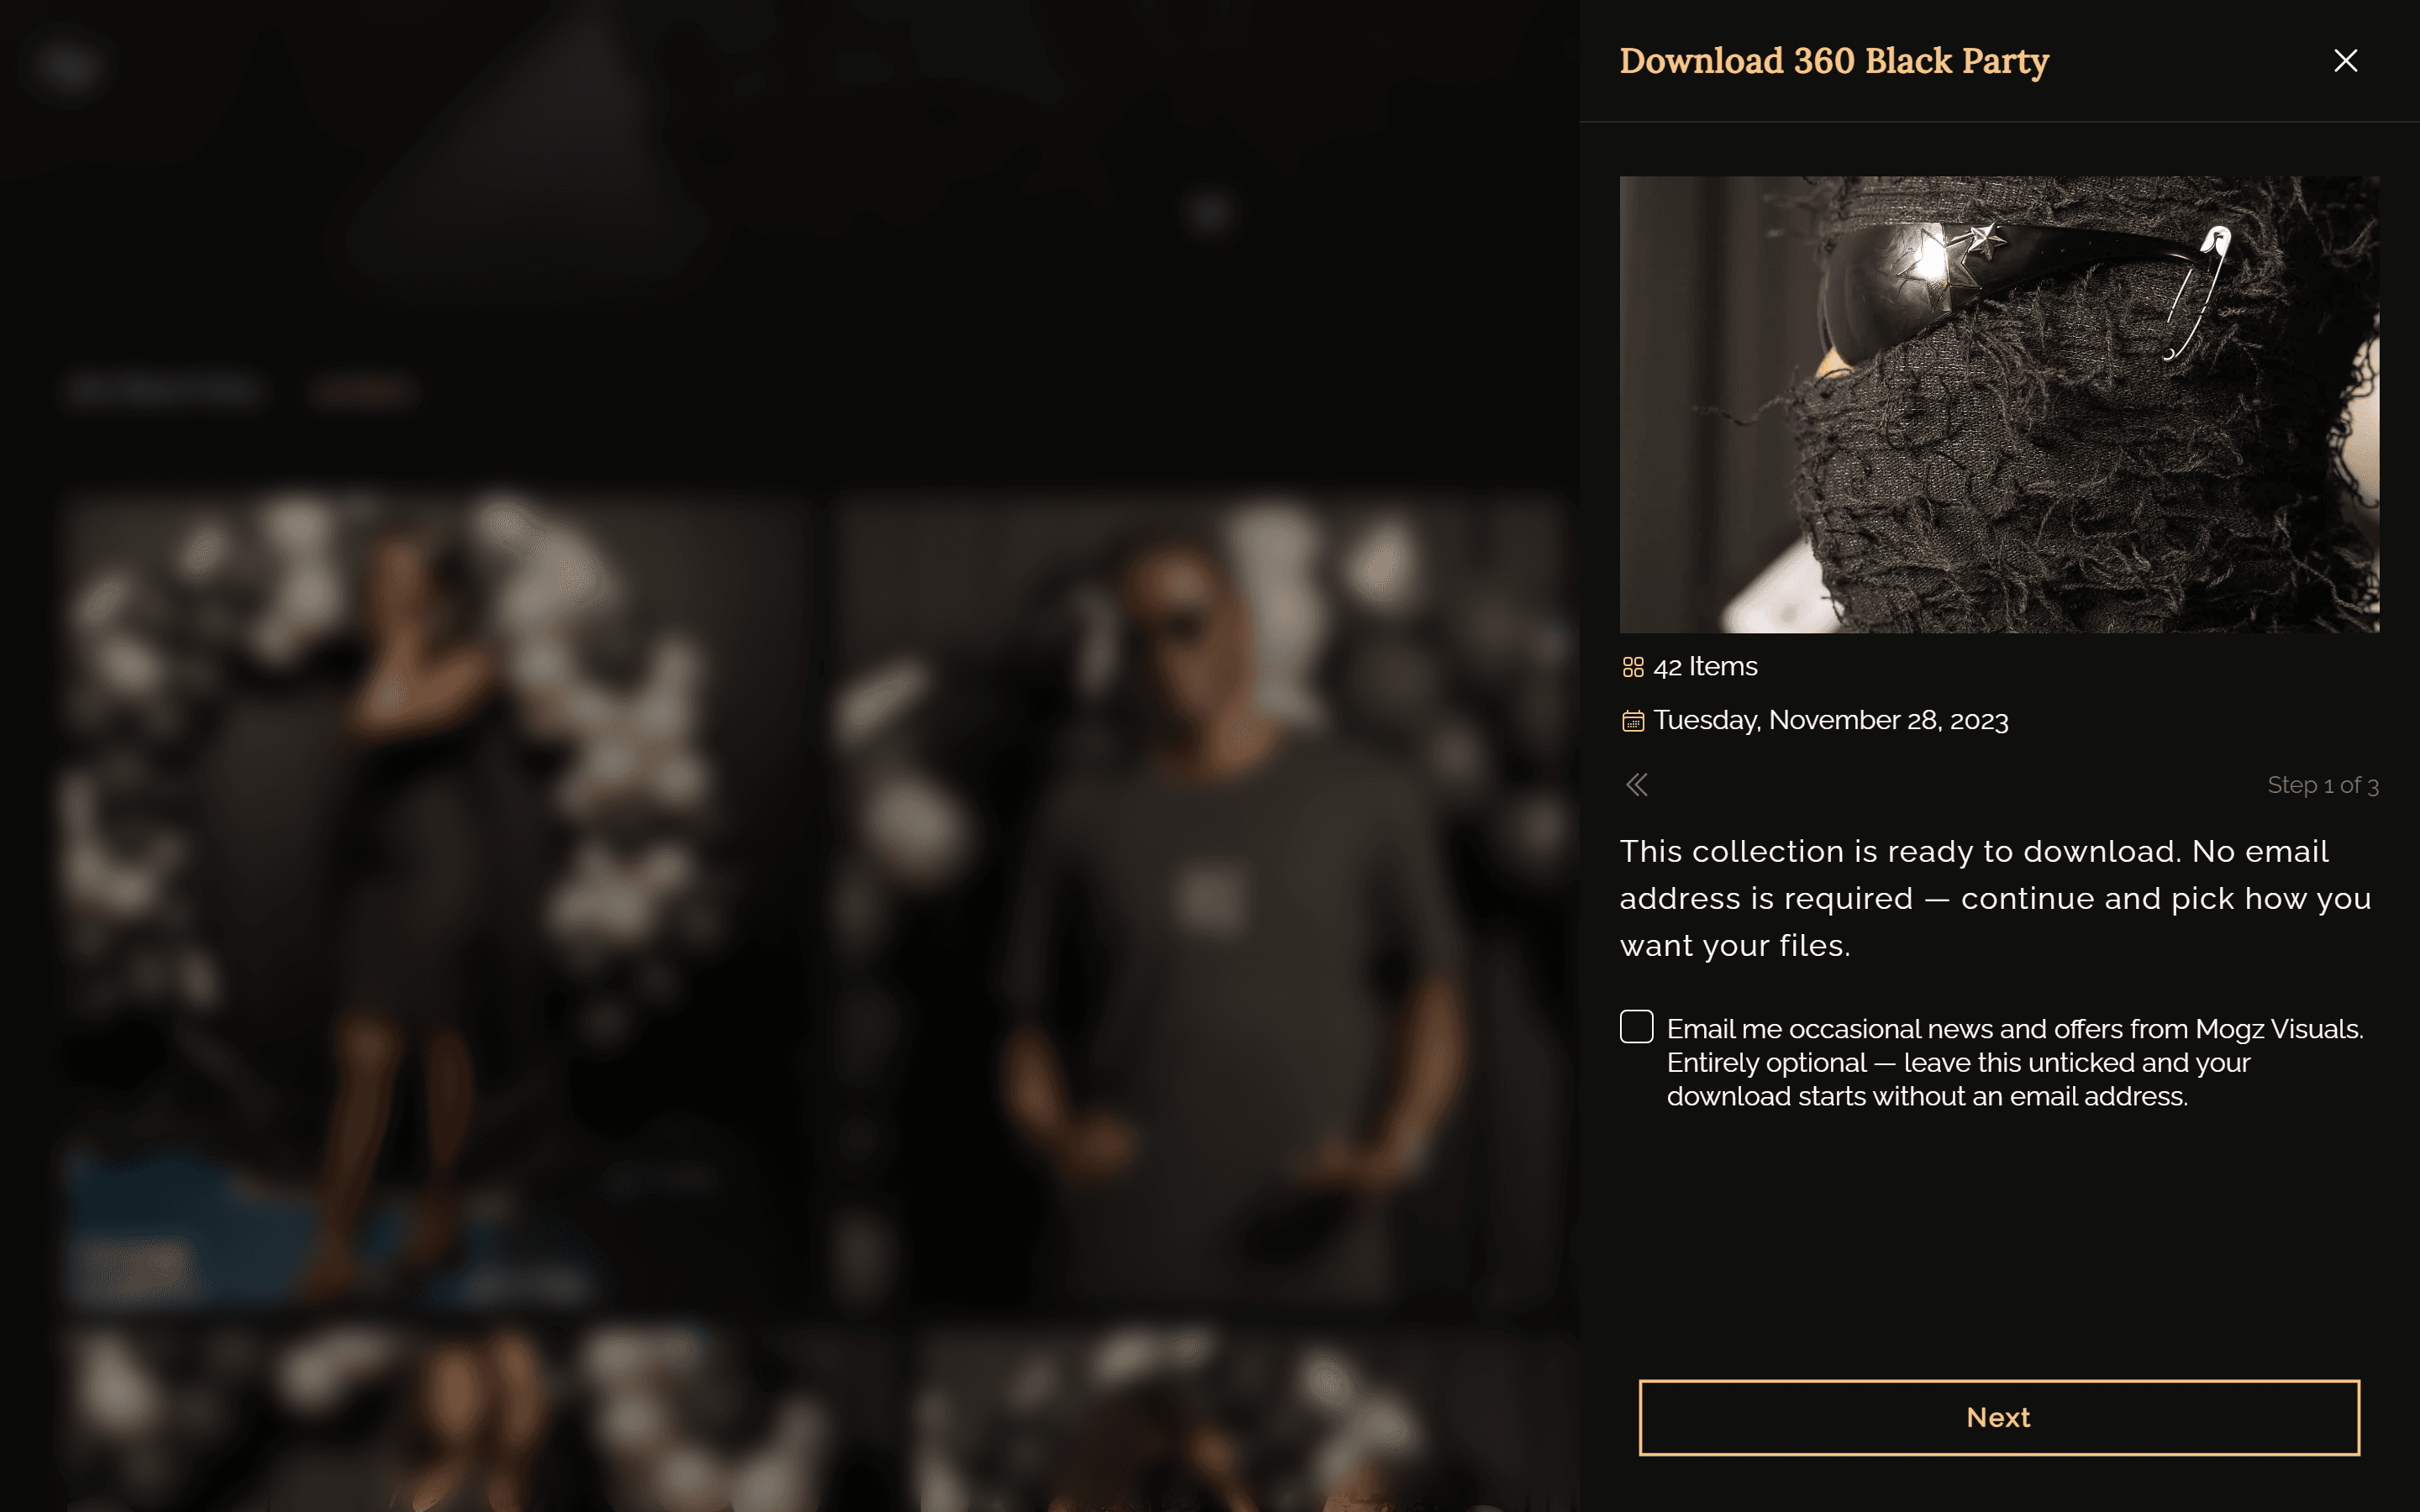
A private download needs the same signed cookie as the gallery. A prepared public archive carries the Sanity document ID it was built from, and the route rechecks that the document is still public before serving the cached file. The check uses the ID, not the slug, because a slug can move to a different collection. A check by slug would then pass for the new collection and still serve the old one's archive. The download drawer used to demand an email before it would do anything. Now it asks for one only if you tick the mailing list box yourself, and the mailing list endpoint has its own rate limit.
07Loading 800 images in batches
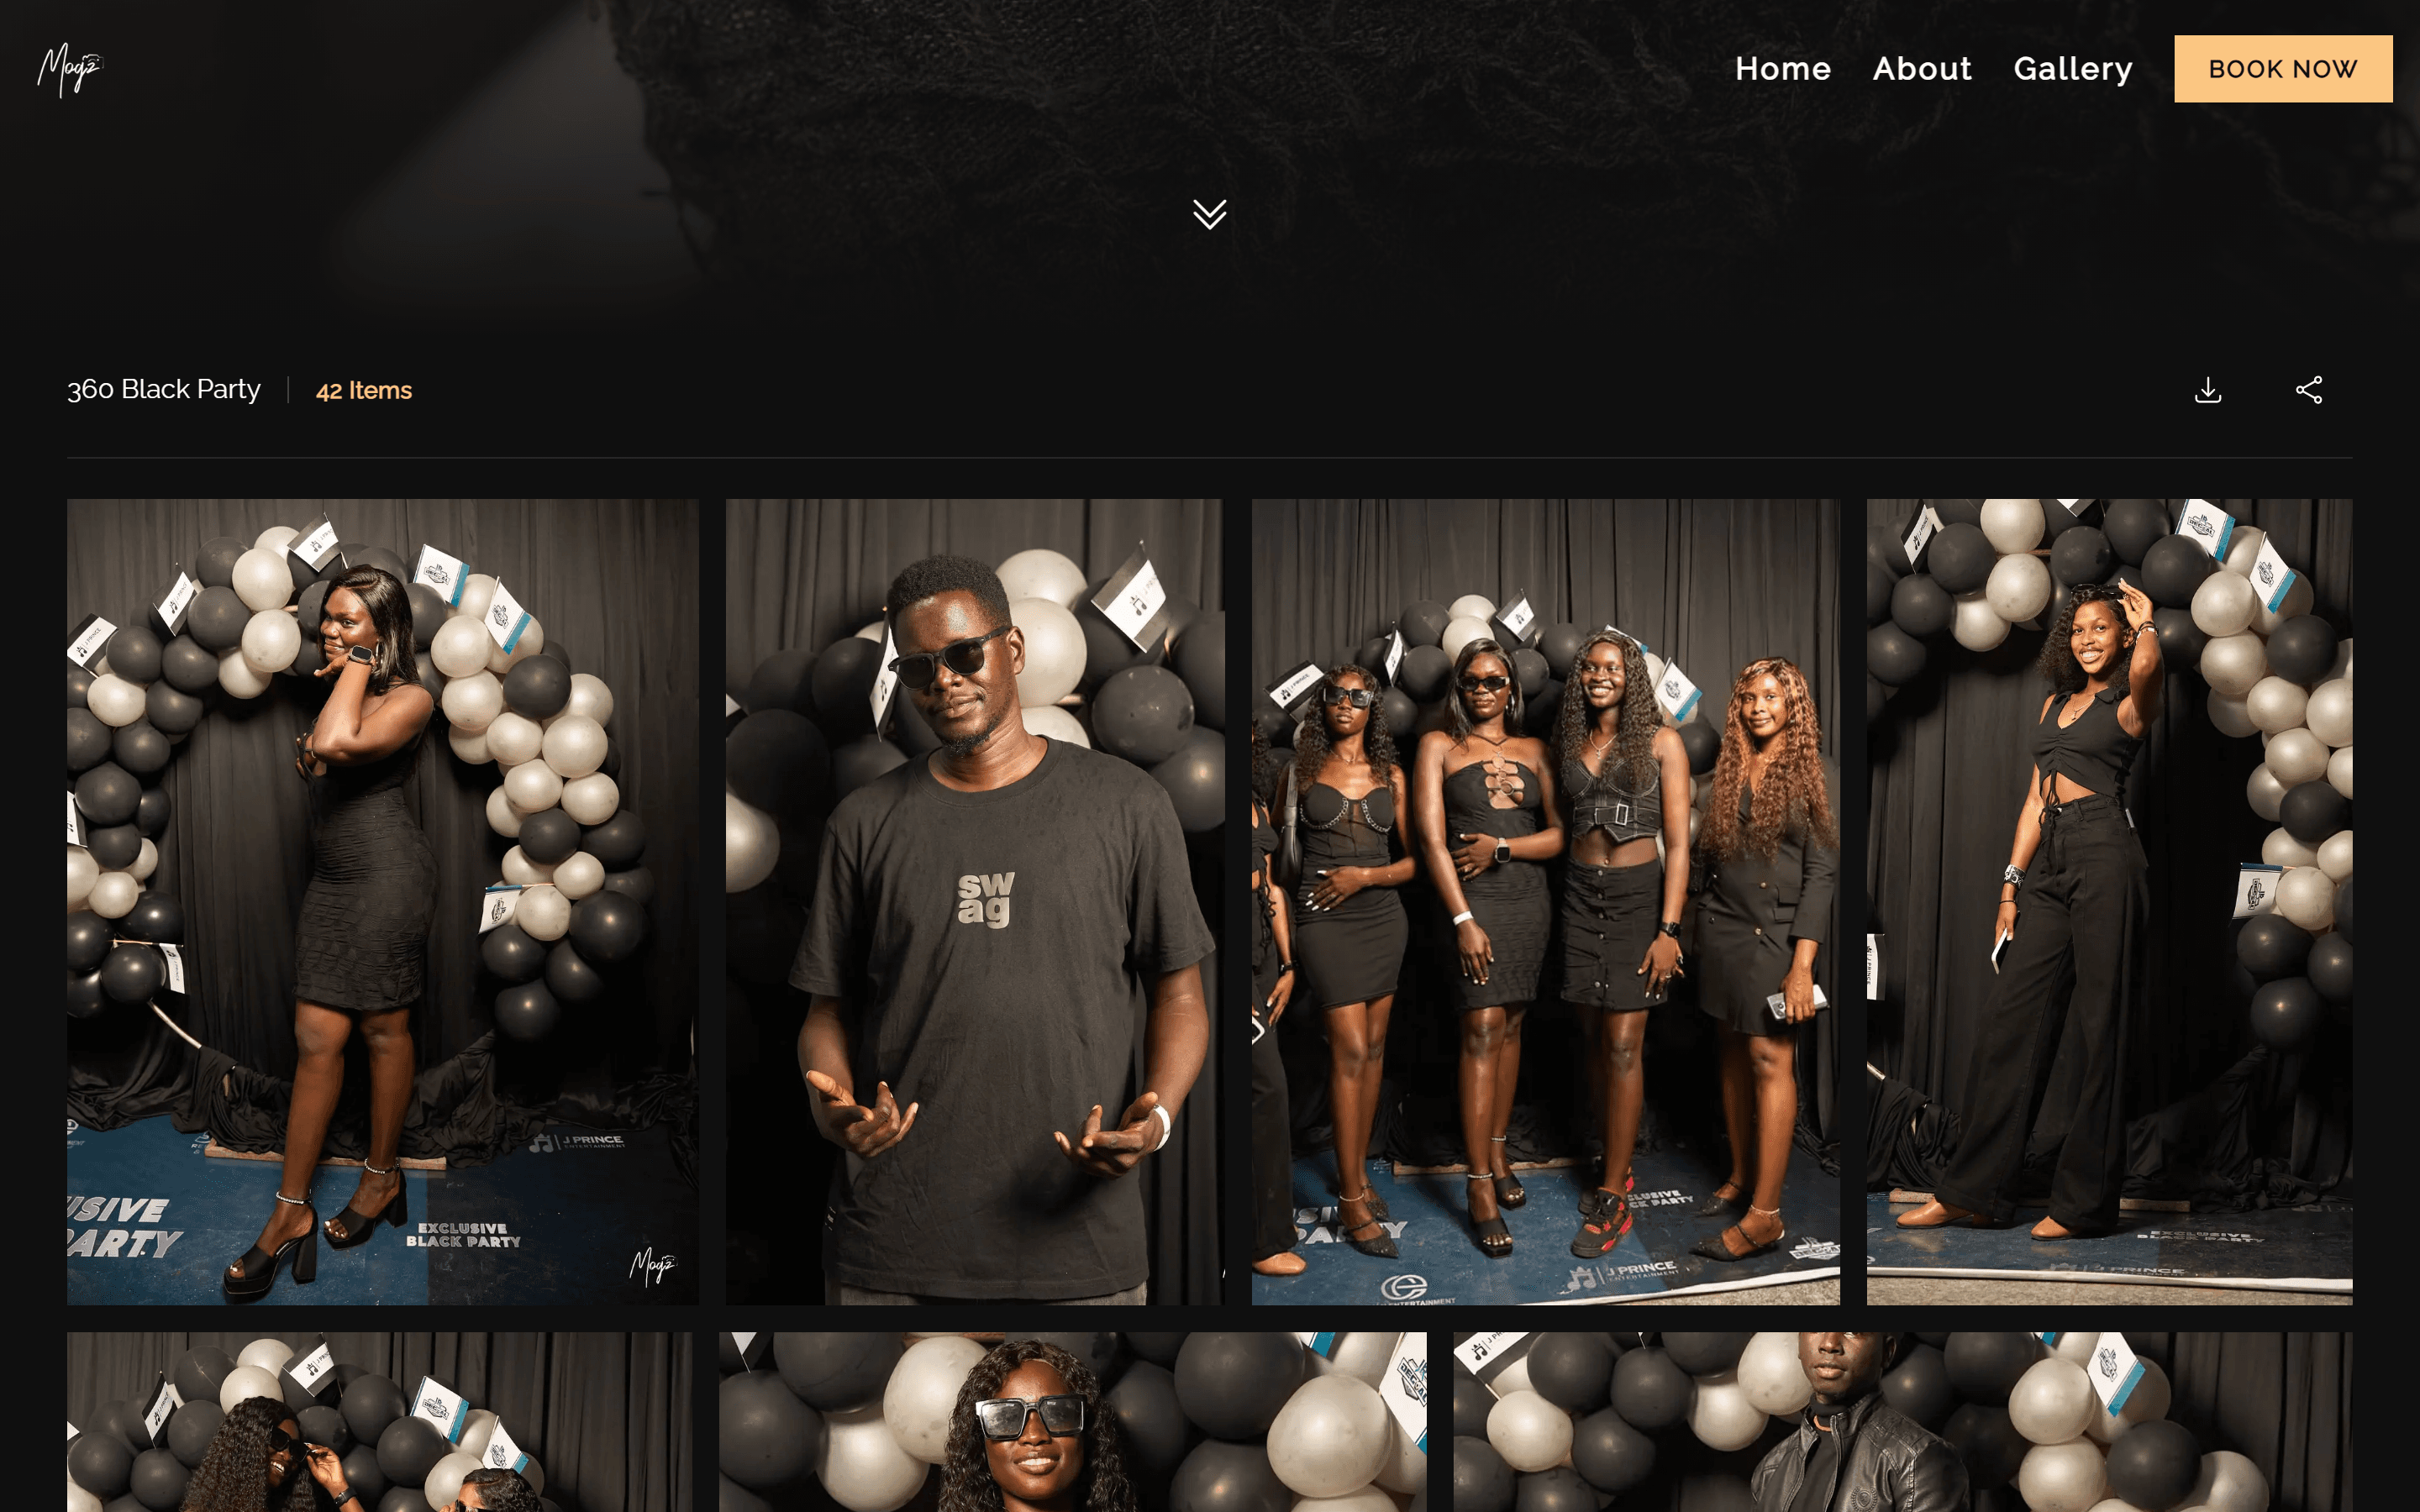
Big collections caused another problem. Loading 800 images at once slowed the first paint and left thumbnails broken far down the page. The gallery now loads in batches of 20 as you scroll, using the same Locomotive Scroll instance to detect the next trigger point.
08Caching on a timer, then on a signal
Every page used to set revalidate = 60. An edit in the Studio took up to a minute to show, and every page re-fetched on a timer whether anything had changed or not. Now Sanity calls /api/revalidate on every content change. The route verifies the webhook signature and rejects a delivery more than five minutes old, so a captured delivery is useless after that. Then it expires the one cache tag that every cached Sanity read shares. Pages keep a daily revalidate as a safety net in case a delivery is lost. The announcement bar is the exception. An announcement can be scheduled to start later, and no webhook fires when that time arrives. So the announcement read refreshes every five minutes on its own.
09A focus pull between pages
With the back end done, I went back to the feel of the site. Page changes were hard cuts, which is a strange thing on a photography site. The transition I settled on is a focus pull. Click a link and the page racks out of focus under a small autofocus reticle, proportioned like a 35mm frame. If the next route is slow, the reticle hunts with a slow pulse in and out. Once the route has committed, the reticle tightens, pauses briefly, and the new page racks in sharp. Phones and weak devices get a lighter blur rather than a fade to black.
Going from a gallery card to its collection works differently. The card's photo morphs into the collection header through the View Transitions API. The header photo starts loading as soon as you hover over, touch, or focus the card, using the same srcset that next/image requests. Until the full photo decodes, the card's own photo shows behind the header, so the morph never lands on a blank hero. Back and Forward get a short fade instead, since visitors use them as a quick undo. Reduced motion gets a brief crossfade.
Most of the work was in what happens when things go wrong. A newer click or a Back press always wins. Before an in-flight transition pushes its route, it checks a generation counter, and if anything newer happened, it reveals onto wherever the visitor actually ended up. A seven-second watchdog reveals the page anyway if a route never commits. If an animation throws, a non-animated reset clears every filter and overlay at once, so a failure cannot leave the page blurred or blocked. The mobile menu slides shut before navigating, and a newer tap while it closes replaces the destination rather than queueing a second trip.
const runCover = useCallback(
  async (href: string) => {
    const lens = routeCover.current;
    if (!lens) {
      router.push(href);
      return;
    }
    busy.current = true;
    const mine = ++generation.current;
    let completed = false;
    try {
      // Listen from the first frame: if Back or another navigation lands
      // while focus is still racking out, reveal onto it and drop this one.
      let pushed = false;
      let superseded = false;
      const routed = waitForRoute(COVER_WATCHDOG_MS, 'resolve').then(() => {
        if (!pushed) superseded = true;
      });

      await lens.cover();
      if (!superseded && generation.current === mine) {
        pushed = true;
        router.push(href);
      }
      const hunt = setTimeout(() => lens.hunt(), HUNT_AFTER_MS);
      await routed;
      clearTimeout(hunt);
      // Let the new page lay out and paint behind the reticle, confirm
      // focus, then rack it in.
      await nextFrame();
      await nextFrame();
      await lens.lock();
      await lens.reveal();
      completed = true;
    } finally {
      // An animation that failed must not leave the page blurred, blocked,
      // or every later navigation treated as mid-transition.
      busy.current = false;
      if (!completed) lens.reset();
    }
  },
  [router, waitForRoute],
);10Checking my own work
Each branch got two independent reviews before it merged, and the findings that held up became regression tests. The site has 165 tests now. I also drove the transitions with Playwright on a local dev server, covering normal navigation and every case I could think of where a newer navigation overtakes one in flight. For each bug fix, I ran its check against the code from before the fix to see it fail there first.
11The case I did not plan for
The site runs on Next.js with Sanity behind it. The part I think about most is the download work. I shipped the happy-path version, watched it fail on a real 850-image gallery, and moved the work from the browser to a worker and then to the server. The lock failed silently for much longer, because a constant-time comparison looks like security even when the value it compares is public. The photos themselves are still readable by anyone who queries the dataset, and I haven't fixed that.